
Android offers built-in support for SQLite, an efficient SQL database. Follow these best practices to optimize your app's performance, ensuring it remains fast and predictably fast as your data grows. By using these best practices, you also reduce the possibility of encountering performance issues that are difficult to reproduce and troubleshoot.
To achieve faster performance, follow these performance principles:
Read fewer rows and columns: Optimize your queries to retrieve only the necessary data. Minimize the amount of data read from the database, because excess data retrieval can impact performance.
Push work to SQLite engine: Perform computations, filtering, and sorting operations within the SQL queries. Using SQLite's query engine can significantly improve performance.
Modify the database schema: Design your database schema to help SQLite construct efficient query plans and data representations. Properly index tables and optimize table structures to enhance performance.
Additionally, you can use the available troubleshooting tools to measure the performance of your SQLite database to help identify areas that require optimization.
We recommend using the Jetpack Room library.
Configure the database for performance
Follow the steps in this section to configure your database for optimal performance in SQLite.
Enable Write-Ahead Logging
SQLite implements mutations by appending them to a log, which it occasionally compacts into the database. This is called Write-Ahead Logging (WAL).
Enable WAL
unless you are using ATTACH DATABASE.
Enable WAL through the framework instead of running PRAGMA journal_mode=WAL
yourself. Room enables WAL by default on devices that aren't low-RAM devices.
Without Room, use one of the following:
- The
enableWriteAheadLoggingmethod - The
ENABLE_WRITE_AHEAD_LOGGINGopen flag - The
setWriteAheadLoggingEnabledmethod ofSQLiteOpenHelper
When the framework knows that the database uses WAL, it opens a pool of
connections so that reads can run concurrently with a write, and it applies the
WAL synchronous mode described in the next section. If you run
PRAGMA journal_mode=WAL yourself, the framework still treats the database as
a rollback journal database. It uses a single connection, and commits keep the
default FULL synchronous mode.
Relax the synchronization mode
SQLite has an option to control synchronous mode. In FULL mode, every
commit issues an fsync to help ensure that the data reaches the disk. This
improves data durability but slows down your commits. With WAL, the NORMAL
mode doesn't sync on every commit and still protects the database from
corruption.
When you enable WAL through the framework, Android applies the device's default
WAL synchronous mode, which is NORMAL in AOSP for Android 9 and higher.
Device manufacturers can change this default, and databases that don't use WAL
default to FULL. To make sure that your database uses NORMAL, set it when
you open the database:
// When opening the database
val params = SQLiteDatabase.OpenParams.Builder()
    .addOpenFlags(SQLiteDatabase.ENABLE_WRITE_AHEAD_LOGGING)
    // SYNC_MODE_NORMAL is available in API level 33 and higher.
    // On API levels 28 to 32, pass "NORMAL" instead.
    .setSynchronousMode(SQLiteDatabase.SYNC_MODE_NORMAL)
    .build()
// With SQLiteOpenHelper, call setOpenParams(params) in your constructor.

// Or: after having opened the database
db.execSQL("PRAGMA synchronous = NORMAL")
In this setting, a commit can return before the data is stored in a disk. If a device shutdown occurs, such as on loss of power or a kernel panic, the committed data might be lost. However, because of logging, your database isn't corrupted.
If only your app crashes, your data still reaches the disk. For most apps, this setting yields performance improvements at no material cost.
Manage connections and memory
Every open database connection holds SQLite memory: a page cache, a lookaside allocator, and a cache of compiled statements. The database file pages also stay in the kernel page cache. Follow the practices in this section to keep this memory in check without slowing down your queries.
Open each database once
Use a single SQLiteOpenHelper or RoomDatabase instance per database file
for your whole process, for example by making it a singleton. Each instance has
its own connection pool, page caches, and statement caches, and two instances
that open the same file can't share them. In one benchmark, consolidating two
helpers that opened the same file into one cut SQLite page cache memory by
almost half and cut p95 query latency by more than half.
To find duplicate instances, check dumpsys dbinfo for the
same database path under more than one Connection pool for heading.
Keep schema changes out of the open callback
The onOpen callback of SQLiteOpenHelper runs every time the database
opens, and so does the onOpen callback of RoomDatabase.Callback. Put
statements such as CREATE TABLE IF NOT EXISTS and CREATE INDEX IF NOT EXISTS
in onCreate and onUpgrade, or in Room migrations. Don't call
setVersion in onOpen, because SQLiteOpenHelper already sets the version
after onCreate and onUpgrade. Even when the schema already exists, these
statements still run on every open, and setVersion writes to the database
file.
Size the prepared statement cache
Android caches compiled statements for each connection. The cache holds 25
statements by default, and you can raise it up to
MAX_SQL_CACHE_SIZE (100) with setMaxSqlCacheSize. If a database
runs more than 25 distinct statements in its hot paths, the cache thrashes and
SQLite compiles the same statements over and over.
First, parameterize your queries. No cache size can
help SQL that's built with string concatenation, because every string is a new
statement. Then check the statement cache hits and misses under POOL STATS in
dumpsys meminfo. For example, the phenotype.db database
in that section's sample output has 147,921 hits and 89,616 misses, which is a
38% miss rate. Raising the cache size on a database like this one can remove
almost all of the misses. Each cached statement uses a few kilobytes of memory.
To raise the cache size, override onConfigure in your SQLiteOpenHelper
subclass:
override fun onConfigure(db: SQLiteDatabase) {
    db.setMaxSqlCacheSize(SQLiteDatabase.MAX_SQL_CACHE_SIZE)
}
If you use Room, call the same method on SupportSQLiteDatabase in the
onOpen callback of RoomDatabase.Callback.
Close idle databases, but keep busy ones open
An open database keeps its connections, caches, and file descriptors even when it's idle. In one benchmark, an idle Room database in WAL mode that stayed open held about 678 KB of SQLite page cache memory and 5 file descriptors. If you only use a database occasionally, for example during a daily sync, close it when you're done.
To close idle databases safely, follow these guidelines:
- Room can close an idle database for you with
setAutoCloseTimeout, which is an experimental API. Room reopens the database on the next access and runs youronOpencallback again, so put any connection configuration there. - Avoid the
setIdleConnectionTimeoutmethods ofSQLiteOpenHelperandSQLiteDatabase.OpenParams.Builder. They're deprecated in API level 29 because they close connections without restoring settings that you applied withPRAGMAstatements. - Don't close a database that you query every few seconds. A timeout that's shorter than the gap between your queries makes the database close and reopen repeatedly, which discards its page cache and statement cache every time and makes the next query slower.
Account for SQLite memory
SQLite memory can be hard to spot. The SQLite page cache and statement cache are
native heap allocations. But Android doesn't enable the memory-mapped I/O of
SQLite by default, so SQLite reads database files with regular file reads, and
the file contents that the kernel caches are unmapped file pages. They don't
count toward your app's PSS in dumpsys meminfo. On devices that use cgroup v2
memory accounting, the kernel still charges these pages to your app's memory
cgroup. To reduce this hidden footprint, read fewer pages by using indexes and
reading only the rows and columns you need. Closing databases you don't need
also frees their SQLite caches.
Define efficient table schemas
To optimize performance and minimize data consumption, define an efficient table schema. SQLite constructs efficient query plans and data, leading to faster data retrieval. This section provides best practices for creating table schemas.
Consider INTEGER PRIMARY KEY
For this example, define and populate a table as follows:
CREATE TABLE Customers(
  id INTEGER,
  name TEXT,
  city TEXT
);
INSERT INTO Customers Values(456, 'John Lennon', 'Liverpool, England');
INSERT INTO Customers Values(123, 'Michael Jackson', 'Gary, IN');
INSERT INTO Customers Values(789, 'Dolly Parton', 'Sevier County, TN');
The table output is as follows:
| rowid | id | name | city |
|---|---|---|---|
| 1 | 456 | John Lennon | Liverpool, England |
| 2 | 123 | Michael Jackson | Gary, IN |
| 3 | 789 | Dolly Parton | Sevier County, TN |
The column rowid is
an index that preserves insertion order. Queries that
filter by rowid are implemented as a fast B-tree search, but queries that
filter by id are a slow table scan.
If you plan on doing lookups by id, you can avoid storing the
rowid column for less data in storage and an overall
faster database:
CREATE TABLE Customers(
  id INTEGER PRIMARY KEY,
  name TEXT,
  city TEXT
);
Your table now looks as follows:
| id | name | city |
|---|---|---|
| 123 | Michael Jackson | Gary, IN |
| 456 | John Lennon | Liverpool, England |
| 789 | Dolly Parton | Sevier County, TN |
Since you don't need to store the rowid column, id queries are fast. Note
that the table is now sorted based on id instead of insertion order.
Accelerate queries with indexes
SQLite uses
indexes
to accelerate queries. When filtering (WHERE), sorting (ORDER BY), or
aggregating (GROUP BY) a column, if the table has an index for the column, the
query is accelerated.
In the previous example, filtering by city requires scanning the entire table:
SELECT id, name
WHERE city = 'London, England';
For an app with a lot of city queries, you can accelerate those queries with an index:
CREATE INDEX city_index ON Customers(city);
An index is implemented as an additional table, sorted by the index column and
mapped to rowid:
| city | rowid |
|---|---|
| Gary, IN | 2 |
| Liverpool, England | 1 |
| Sevier County, TN | 3 |
Note that the storage cost of the city column is now double, because it's
now present in both the original table and the index. Since you are using the
index, the cost of added storage is worth the benefit of faster queries.
However, don't maintain an index that you're not using to avoid paying the
storage cost for no query performance gain.
Create multi-column indexes
If your queries combine multiple columns, you can create multi-column indexes to fully accelerate the query. You can also use an index on an outside column and let the inside search be done as a linear scan.
For example, given the following query:
SELECT id, name
WHERE city = 'London, England'
ORDER BY city, name
You can accelerate the query with a multi-column index in the same order as specified in the query:
CREATE INDEX city_name_index ON Customers(city, name);
However, if you only have an index on city, the outside ordering is still
accelerated, while the inside ordering requires a linear scan.
This also works with prefix inquiries. For example, an index
ON Customers (city, name) also accelerates filtering, ordering, and grouping
by city, since the index table for a multi-column index is ordered by the
given indexes in the given order.
Consider WITHOUT ROWID
By default, SQLite creates a rowid column for your table, where rowid is an
implicit INTEGER PRIMARY KEY AUTOINCREMENT. If you already have a column that
is INTEGER PRIMARY KEY, then this column becomes an alias of rowid.
For tables that have a primary key other than INTEGER or a composite of
columns, consider WITHOUT ROWID.
Store small data as a BLOB and large data as a file
If you want to associate large data with a row, such as a thumbnail of an image
or a photo for a contact, you can store the data either in a BLOB column or in
a file, and then store the path in the column.
Files are generally rounded up to 4 KB increments. For very small files, where
the rounding error is significant, it's more efficient to store them in the
database as a BLOB. SQLite minimizes file system calls and is
faster than the underlying filesystem in some cases.
Improve query performance
Follow these best practices to improve query performance in SQLite by minimizing response times and maximizing processing efficiency.
Read only the rows you need
Filters let you narrow down your results by specifying certain criteria, such as date range, location, or name. Limits let you control the number of results you see:
db.rawQuery("""
    SELECT name
    FROM Customers
    LIMIT 10;
    """.trimIndent(),
    null
).use { cursor ->
    while (cursor.moveToNext()) {
        // Process cursor data
    }
}
Read only the columns you need
Avoid selecting unneeded columns, which can slow down your queries and waste resources. Instead, only select columns that are used.
In the following example, you select id, name, and phone:
// This is not the most efficient way of doing this.
// See the following example for a better approach.

db.rawQuery(
    """
    SELECT id, name, phone
    FROM customers;
    """.trimIndent(),
    null
).use { cursor ->
    while (cursor.moveToNext()) {
        val name = cursor.getString(1)
        // Further processing
    }
}
However, you only need the name column:
db.rawQuery("""
    SELECT name
    FROM Customers;
    """.trimIndent(),
    null
).use { cursor ->
    while (cursor.moveToNext()) {
        val name = cursor.getString(0)
        // Further processing
    }
}
Parameterize queries
Your query string might include a parameter that is only known at runtime, such as the following:
fun getNameById(id: Long): String?
    db.rawQuery(
        "SELECT name FROM customers WHERE id=$id", null
    ).use { cursor ->
        return if (cursor.moveToFirst()) {
            cursor.getString(0)
        } else {
            null
        }
    }
}
In the preceding code, every query constructs a different string, and thus
doesn't benefit from the statement cache. Each call requires SQLite to compile
it before it can execute. Instead, you can replace the id argument with a
parameter and
bind the value with selectionArgs:
fun getNameById(id: Long): String? {
    db.rawQuery(
        """
          SELECT name
          FROM customers
          WHERE id=?
        """.trimIndent(), arrayOf(id.toString())
    ).use { cursor ->
        return if (cursor.moveToFirst()) {
            cursor.getString(0)
        } else {
            null
        }
    }
}
Now the query can be compiled once and cached. The compiled query is reused
between different invocations of getNameById(long).
Iterate in SQL, not in code
Use a single query that returns all targeted results, instead of a programmatic loop iterating on SQL queries to return individual results. The programmatic loop is about 1000 times slower than a single SQL query.
Use DISTINCT for unique values
Using the DISTINCT keyword can improve the performance of your queries by
reducing the amount of data that needs to be processed. For example, if you want
to return only the unique values from a column, use DISTINCT:
db.rawQuery("""
    SELECT DISTINCT name
    FROM Customers;
    """.trimIndent(),
    null
).use { cursor ->
    while (cursor.moveToNext()) {
        // Only iterate over distinct names in Kotlin
        // Process distinct name
    }
}
Use aggregate functions whenever possible
Use aggregate functions for aggregate results without row data. For example, the following code checks whether there is at least one matching row:
// This is not the most efficient way of doing this.
// See the following example for a better approach.

db.rawQuery("""
    SELECT id, name
    FROM Customers
    WHERE city = 'Paris';
    """.trimIndent(),
    null
).use { cursor ->
    if (cursor.moveToFirst()) {
        // At least one customer from Paris
        // Handle found
    } else {
        // No customers from Paris
        // Handle not found
}
To only fetch the first row, you can use EXISTS() to return 0 if a matching
row does not exist and 1 if one or more rows match:
db.rawQuery("""
    SELECT EXISTS (
        SELECT null
        FROM Customers
        WHERE city = 'Paris';
    );
    """.trimIndent(),
    null
).use { cursor ->
    if (cursor.moveToFirst() && cursor.getInt(0) == 1) {
        // At least one customer from Paris
        // Handle found
    } else {
        // No customers from Paris
        // Handle not found
    }
}
Use SQLite aggregate functions in your app code:
COUNT: counts how many rows are in a column.SUM: adds all numerical values in a column.MINorMAX: determines the lowest or highest value. Works for numeric columns,DATEtypes, and text types.AVG: finds the average numerical value.GROUP_CONCAT: concatenates strings with an optional separator.
Use COUNT() instead of Cursor.getCount()
In the
following example, the
Cursor.getCount() function
reads all the rows from the database and returns all the row values:
// This is not the most efficient way of doing this.
// See the following example for a better approach.

db.rawQuery("""
    SELECT id
    FROM Customers;
    """.trimIndent(),
    null
).use { cursor ->
    val count = cursor.getCount()
    // Use count
}
However, by using COUNT(), the database returns only the
count:
db.rawQuery("""
    SELECT COUNT(*)
    FROM Customers;
    """.trimIndent(),
    null
).use { cursor ->
    cursor.moveToFirst()
    val count = cursor.getInt(0)
    // Use count
}
Nest queries instead of code
SQL is composable and supports subqueries, joins, and foreign key constraints. You can use the result of one query in another query without going through app code. This reduces the need to copy data from SQLite and lets the database engine optimize your query.
In the following example, you can run a query to find which city has the most customers, then use the result in another query to find all the customers from that city:
// This is not the most efficient way of doing this.
// See the following example for a better approach.

db.rawQuery("""
    SELECT city
    FROM Customers
    GROUP BY city
    ORDER BY COUNT(*) DESC
    LIMIT 1;
    """.trimIndent(),
    null
).use { cursor ->
    if (cursor.moveToFirst()) {
        val topCity = cursor.getString(0)
        db.rawQuery("""
            SELECT name, city
            FROM Customers
            WHERE city = ?;
        """.trimIndent(),
        arrayOf(topCity)).use { innerCursor ->
            while (innerCursor.moveToNext()) {
                // Process inner cursor data
            }
        }
    }
}
To get the result in half the time of the previous example, use a single SQL query with nested statements:
db.rawQuery("""
    SELECT name, city
    FROM Customers
    WHERE city IN (
        SELECT city
        FROM Customers
        GROUP BY city
        ORDER BY COUNT (*) DESC
        LIMIT 1;
    );
    """.trimIndent(),
    null
).use { cursor ->
    if (cursor.moveToNext()) {
        // Process cursor data
    }
}
Check uniqueness in SQL
If a row must not be inserted unless a particular column value is unique in the table, then it might be more efficient to enforce that uniqueness as a column constraint.
In the following example, one query is run to validate the row to be inserted and another to actually insert:
// This is not the most efficient way of doing this.
// See the following example for a better approach.

db.rawQuery(
    """
    SELECT EXISTS (
        SELECT null
        FROM customers
        WHERE username = ?
    );
    """.trimIndent(),
    arrayOf(customer.username)
).use { cursor ->
    if (cursor.moveToFirst() && cursor.getInt(0) == 1) {
        throw AddCustomerException(customer)
    }
}
db.execSQL(
    "INSERT INTO customers VALUES (?, ?, ?)",
    arrayOf(
        customer.id.toString(),
        customer.name,
        customer.username
    )
)
Instead of checking the unique constraint in Kotlin, you can check it in SQL when you define the table:
CREATE TABLE Customers(
  id INTEGER PRIMARY KEY,
  name TEXT,
  username TEXT UNIQUE
);
SQLite does the same as the following:
CREATE TABLE Customers(...);
CREATE UNIQUE INDEX CustomersUsername ON Customers(username);
Now you can insert a row and let SQLite check the constraint:
try {
    db.execSQL(
        "INSERT INTO Customers VALUES (?, ?, ?)",
        arrayOf(customer.id.toString(), customer.name, customer.username)
    )
} catch(e: SQLiteConstraintException) {
    throw AddCustomerException(customer, e)
}
SQLite supports unique indexes with multiple columns:
CREATE TABLE table(...);
CREATE UNIQUE INDEX unique_table ON table(column1, column2, ...);
SQLite validates constraints faster and with less overhead than Kotlin code. It is a best practice to use SQLite rather than app code.
Batch multiple insertions in a single transaction
A transaction commits multiple operations, which improves not only efficiency but also correctness. To improve data consistency and accelerate performance, you can batch insertions:
db.beginTransaction()
try {
    customers.forEach { customer ->
        db.execSQL(
            "INSERT INTO Customers VALUES (?, ?, ?)",
            arrayOf(customer.id.toString(), customer.name, "customerValue")
        )
    }
    db.setTransactionSuccessful()
} finally {
    db.endTransaction()
}
Outside of an explicit transaction, each write runs in its own implicit
transaction and pays the full cost of a commit, including an fsync in FULL
synchronous mode. Batching pays that cost once, which can make a batch of
writes an order of magnitude or more faster.
Use troubleshooting tools
SQLite provides the following troubleshooting tools to help measure performance.
Use SQLite's interactive prompt
Run SQLite on your machine to run queries and learn.
Different Android platform versions use different revisions of SQLite. To use
the same engine that's on an Android-powered device, use adb shell and
run sqlite3 on your target device.
You can ask SQLite to time queries:
sqlite> .timer on
sqlite> SELECT ...
Run Time: real ... user ... sys ...
EXPLAIN QUERY PLAN
You can ask SQLite to explain how it intends to answer a query by using
EXPLAIN QUERY PLAN:
sqlite> EXPLAIN QUERY PLAN
SELECT id, name
FROM Customers
WHERE city = 'Paris';
QUERY PLAN
`--SCAN Customers
The previous example requires a full table scan without an index to find all customers from Paris. This is called linear complexity. SQLite needs to read all the rows and only keep the rows that match customers from Paris. To fix this, you can add an index:
sqlite> CREATE INDEX Idx1 ON Customers(city);
sqlite> EXPLAIN QUERY PLAN
SELECT id, name
FROM Customers
WHERE city = 'Paris';
QUERY PLAN
`--SEARCH test USING INDEX Idx1 (city=?
If you're using the interactive shell, you can ask SQLite to always explain query plans:
sqlite> .eqp on
For more information, see Query Planning.
SQLite Analyzer
SQLite offers the sqlite3_analyzer command-line interface (CLI) to dump
additional information that can be used to troubleshoot performance. To install,
visit the SQLite Download Page.
You can use adb pull to download a database file from a target device to your
workstation for analysis:
adb pull /data/data/<app_package_name>/databases/<db_name>.db
SQLite Browser
You can also install the GUI tool SQLite Browser on the SQLite Downloads page.
Android logging
Android times SQLite queries and logs them for you:
# Enable query time logging
$ adb shell setprop log.tag.SQLiteTime VERBOSE
# Disable query time logging
$ adb shell setprop log.tag.SQLiteTime ERROR
In Android 13 and higher, you can also log only the slow operations. Set a threshold in milliseconds, then restart your app so that it reads the log tag:
$ adb shell setprop log.tag.SQLiteSlowQueries VERBOSE
$ adb shell setprop db.log.slow_query_threshold 100
$ adb shell am force-stop <package-name>
Slow operations appear in logcat under the SQLiteConnection tag with their
duration, SQL, and database path. To set the threshold for a single app, use
db.log.slow_query_threshold.<uid>, where <uid> is the UID of the app.
Perfetto tracing
When configuring Perfetto, add the database atrace category to include
SQLite operations in the trace. To see what each thread is doing while it runs
SQL, also add the scheduler events:
data_sources {
  config {
    name: "linux.ftrace"
    ftrace_config {
      ftrace_events: "sched/sched_switch"
      ftrace_events: "sched/sched_waking"
      ftrace_events: "sched/sched_blocked_reason"
      atrace_categories: "database"
    }
  }
}
Android traces each database operation as a slice named after the operation
and its SQL, for example
executeForCursorWindow SELECT * FROM message WHERE body LIKE ?. The SQL keeps
its ? placeholders and is truncated to 256 characters. Bind arguments aren't
included. Operations include open, close, prepare, execute, and the
executeFor variants. A prepare slice doesn't mean that the statement cache
missed.
The track layout depends on the Android version:
- In Android 17 and higher, each connection has an async track in the app
process named
SQLiteConnection-followed by a connection number. Transactions appear asTRANSACTION-EXCLUSIVE,TRANSACTION-IMMEDIATE, orTRANSACTION-DEFERREDslices, with the statements that ran in them nested underneath. The thread that runs an operation also getsSTART-andEND-instant events on its thread track, for every transaction and for every statement outside a transaction. The names of these events end with the connection track name, for example-SQLiteConnection-0. - In Android 16 and lower, each distinct SQL statement has its own async track in the app process, and transactions aren't traced.
Connection numbers restart at 0 for each database, so the primary connections
of all the databases in a process share the SQLiteConnection-0 track. If your
app uses more than one database at the same time, measure durations with the
START- and END- events on the thread tracks.
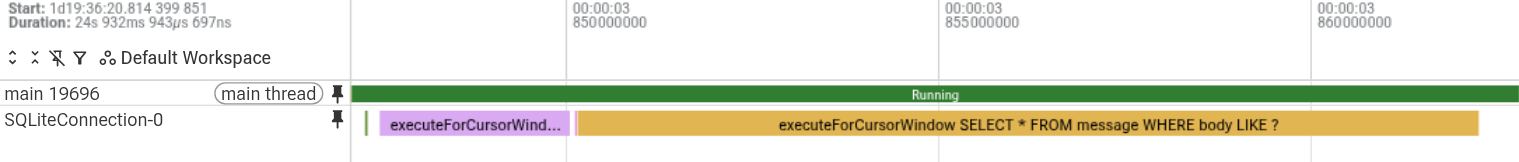
Figure 1. A full table scan on the main thread in Android 17.
You can analyze these slices with PerfettoSQL in the Perfetto UI or with
trace_processor. The following query finds the most frequent SQLite
operations in each process. This query works on all Android versions:
INCLUDE PERFETTO MODULE slices.with_context;

SELECT process_name, name AS operation, COUNT(*) AS count
FROM process_slice
WHERE name GLOB 'open *' OR name GLOB 'close *'
  OR name GLOB 'prepare *' OR name GLOB 'execute*'
  OR name GLOB 'TRANSACTION-*'
GROUP BY process_name, name
ORDER BY count DESC
LIMIT 10;
The following query lists SQLite operations that took longer than 1 ms on a main thread in Android 17 and higher:
INCLUDE PERFETTO MODULE slices.with_context;

WITH marks AS (
  SELECT process_name, utid, is_main_thread, ts, name,
    LEAD(ts) OVER (PARTITION BY utid ORDER BY ts) AS end_ts,
    LEAD(name) OVER (PARTITION BY utid ORDER BY ts) AS end_name
  FROM thread_slice
  WHERE name GLOB 'START-*' OR name GLOB 'END-*'
)
SELECT process_name, ts, ROUND((end_ts - ts) / 1e6, 1) AS dur_ms,
  substr(name, 7) AS operation
FROM marks
WHERE name GLOB 'START-*'
  AND end_name = 'END-' || substr(name, 7)
  AND is_main_thread
  AND end_ts - ts > 1e6
ORDER BY dur_ms DESC
LIMIT 10;
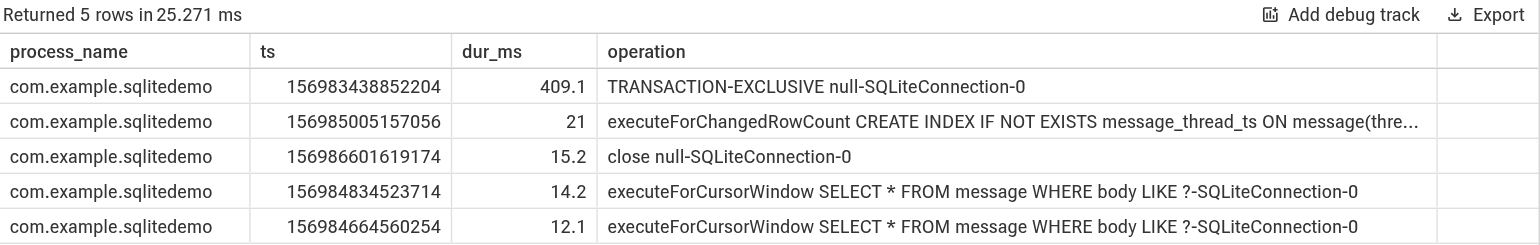
Figure 2. SQLite operations longer than 1 ms on a main thread.
The following query finds threads that write outside an explicit transaction, where every write pays for its own commit, in Android 17 and higher:
INCLUDE PERFETTO MODULE slices.with_context;

WITH ops AS (
  SELECT process_name, thread_name, utid, name,
    upper(ltrim(substr(name, instr(name, ' ') + 1))) AS sql
  FROM thread_slice
  WHERE name GLOB 'START-*'
)
SELECT process_name, thread_name,
  SUM(name GLOB 'START-TRANSACTION-*') AS transactions,
  SUM(name GLOB 'START-execute*' AND (sql GLOB 'INSERT *'
    OR sql GLOB 'UPDATE *' OR sql GLOB 'DELETE *' OR sql GLOB 'REPLACE *'))
    AS autocommit_writes
FROM ops
GROUP BY utid
HAVING autocommit_writes > 0
ORDER BY autocommit_writes DESC
LIMIT 10;
dumpsys meminfo
adb shell dumpsys meminfo <package-name> prints stats related to the app's
memory usage, including details about SQLite in the DATABASES section. For
example, this was taken from the output of
adb shell dumpsys meminfo com.google.android.gms.persistent on a developer's
device:
DATABASES
      pgsz     dbsz   Lookaside(b) cache hits cache misses cache size  Dbname
PER CONNECTION STATS
         4       52             45     8    41     6  /data/user/10/com.google.android.gms/databases/gaia-discovery
         4        8                    0     0     0    (attached) temp
         4       52             56     5    23     6  /data/user/10/com.google.android.gms/databases/gaia-discovery (1)
         4      252             95   233   124    12  /data/user_de/10/com.google.android.gms/databases/phenotype.db
         4        8                    0     0     0    (attached) temp
         4      252             17     0    17     1  /data/user_de/10/com.google.android.gms/databases/phenotype.db (1)
         4     9280            105 103169 69805    25  /data/user/10/com.google.android.gms/databases/phenotype.db
         4       20                    0     0     0    (attached) temp
         4     9280            108 13877  6394    25  /data/user/10/com.google.android.gms/databases/phenotype.db (2)
         4        8                    0     0     0    (attached) temp
         4     9280            105 12548  5519    25  /data/user/10/com.google.android.gms/databases/phenotype.db (3)
         4        8                    0     0     0    (attached) temp
         4     9280            107 18328  7886    25  /data/user/10/com.google.android.gms/databases/phenotype.db (1)
         4        8                    0     0     0    (attached) temp
         4       36             51   156    29     5  /data/user/10/com.google.android.gms/databases/mobstore_gc_db_v0
         4       36             97    47    27    10  /data/user/10/com.google.android.gms/databases/context_feature_default.db
         4       36             56     3    16     4  /data/user/10/com.google.android.gms/databases/context_feature_default.db (2)
         4      300             40  2111    24     5  /data/user/10/com.google.android.gms/databases/gservices.db
         4      300             39     3    17     4  /data/user/10/com.google.android.gms/databases/gservices.db (1)
         4       20             17     0    14     1  /data/user/10/com.google.android.gms/databases/gms.notifications.db
         4       20             33     1    15     2  /data/user/10/com.google.android.gms/databases/gms.notifications.db (1)
         4      120             40   143   163     4  /data/user/10/com.google.android.gms/databases/android_pay
         4      120            123    86    32    19  /data/user/10/com.google.android.gms/databases/android_pay (1)
         4       28             33     4    17     3  /data/user/10/com.google.android.gms/databases/googlesettings.db
POOL STATS
     cache hits  cache misses    cache size  Dbname
             13            68            81  /data/user/10/com.google.android.gms/databases/gaia-discovery
            233           145           378  /data/user_de/10/com.google.android.gms/databases/phenotype.db
         147921         89616        237537  /data/user/10/com.google.android.gms/databases/phenotype.db
            156            30           186  /data/user/10/com.google.android.gms/databases/mobstore_gc_db_v0
             50            57           107  /data/user/10/com.google.android.gms/databases/context_feature_default.db
           2114            43          2157  /data/user/10/com.google.android.gms/databases/gservices.db
              1            31            32  /data/user/10/com.google.android.gms/databases/gms.notifications.db
            229           197           426  /data/user/10/com.google.android.gms/databases/android_pay
              4            18            22  /data/user/10/com.google.android.gms/databases/googlesettings.db
Android 14 and higher print the PER CONNECTION STATS and POOL STATS tables
shown in the example. Android 13 and lower print only the per-connection table,
with the cache stats combined into a single cache column as
hits/misses/size.
Under PER CONNECTION STATS, you'll find:
pgsz: the size of one database page, in KB.dbsz: the size of the entire database file, in KB.Lookaside(b): the number of lookaside memory slots that the connection uses. Despite the(b)in the header, this is a count of slots, not bytes.cache hits,cache misses, andcache size: stats for the prepared statement cache of the connection. These values count compiled SQL statements, not database pages.Dbname: the path to the database file. Additional connections to the same database have a number in parentheses appended, such as(1). With WAL, a database can have several connections so that reads can run in parallel.
Under POOL STATS, you'll find the prepared statement cache stats for each
connection pool:
cache hits: SQLite caches prepared statements and attempts to reuse them when running queries, to save some effort and memory in compiling SQL statements. This is the number of statement cache hits.cache misses: the number of statement cache misses.cache size: in Android 16 QPR2 and higher, the number of prepared statements in the cache, summed across the idle connections of the pool. In Android 14 through Android 16 QPR1, this value is the sum of hits and misses, and doesn't represent the cache size.
Use these stats to decide what to fix:
- A high miss rate means that SQLite compiles the same statements repeatedly.
First, look for SQL that's built with string concatenation and
parameterize it. If your queries are already
parameterized and the per-connection
cache sizeis at the limit of 25, raise the cache size. - A database path that appears more than once without a
(1)-style suffix means that your app opened the same file twice. Open each database once. - A database that your app rarely uses still holds memory while it's open. Close it when you're done.
dumpsys dbinfo
adb shell dumpsys dbinfo <package-name> prints the state of every connection
pool in your app. Add -v to also list the statements in the prepared
statement cache of each connection. The following example output is from
Android 17, with paths and long lines shortened:
** Database info for pid 2705 [com.example.app] **
Connection pool for /data/user/0/com.example.app/databases/settings.db:
  Open: true
  Max connections: 4
  Total execution time (ms): 4963
  Total statements executed: 231239
  Average time per statement (ms): 0
  Configuration: openFlags=805306368, ..., journalMode=WAL, syncMode=NORMAL
  IsReadOnlyDatabase: false
  Available primary connection:
    <none>
  Available non-primary connections:
    <none>
  Acquired connections:
    <none>
  Connection waiters:
    <none>
Connection pool for /data/user/0/com.example.app/databases/events.db:
  Open: true
  Max connections: 1
  Total execution time (ms): 842
  Total statements executed: 840
  Average time per statement (ms): 1
  Configuration: openFlags=268435456, ..., journalMode=TRUNCATE, syncMode=FULL
  IsReadOnlyDatabase: false
  Available primary connection:
    Connection #0:
      isPrimaryConnection: true
      onlyAllowReadOnlyOperations: false
      totalLongOperations: 0
      Most recently executed operations:
        0: [10-26 04:22:32.133] executeForChangedRowCount took 0ms -
           succeeded, sql="DELETE FROM params WHERE app_id=?", path=...
        1: [10-26 04:22:32.133] prepare took 0ms - succeeded,
           sql="DELETE FROM params WHERE app_id=?", path=...
        ...
Look for the following:
Configuration: the journal mode and synchronous mode of the pool. In Android 13 and higher, this line shows the modes that the framework applied, including platform defaults. In the example,events.dbuses the rollback journal withFULLsynchronous mode, so every commit waits for a full sync. This line doesn't reflectPRAGMAstatements that you run yourself.Max connections: a value of 1 for a writable database means that the framework doesn't consider the database to be in WAL mode, so reads and writes share a single connection.Total execution time,Total statements executed, andAverage time per statement: available in Android 13 and higher. Use them to find your busiest databases.Most recently executed operations: the last 20 operations on each connection, with their duration and SQL. Look for patterns such as the same query running in a loop, or many writes in a row outside of a transaction. In Android 15 QPR1 and higher, this list also includes explicit transactions.totalLongOperationsandOperations exceeding 2000ms: available in Android 15 QPR1 and higher. They show how many operations and transactions took longer than 2 seconds, and list the last 10 of them.Acquired connectionsandConnection waiters: connections that are in use and threads that are waiting for a connection. Waiters indicate contention, such as a long write transaction that blocks other writes.Prepared statement cache: printed with-v. Many entries that differ only in literal values point to SQL that's built with string concatenation.- The same path under more than one
Connection pool forheading means that your app opened the same file twice.
Additional resources
Views content
Recommended for you
- Note: link text is displayed when JavaScript is off
- Run benchmarks in Continuous Integration
- Frozen frames
- Create and measure Baseline Profiles without Macrobenchmark